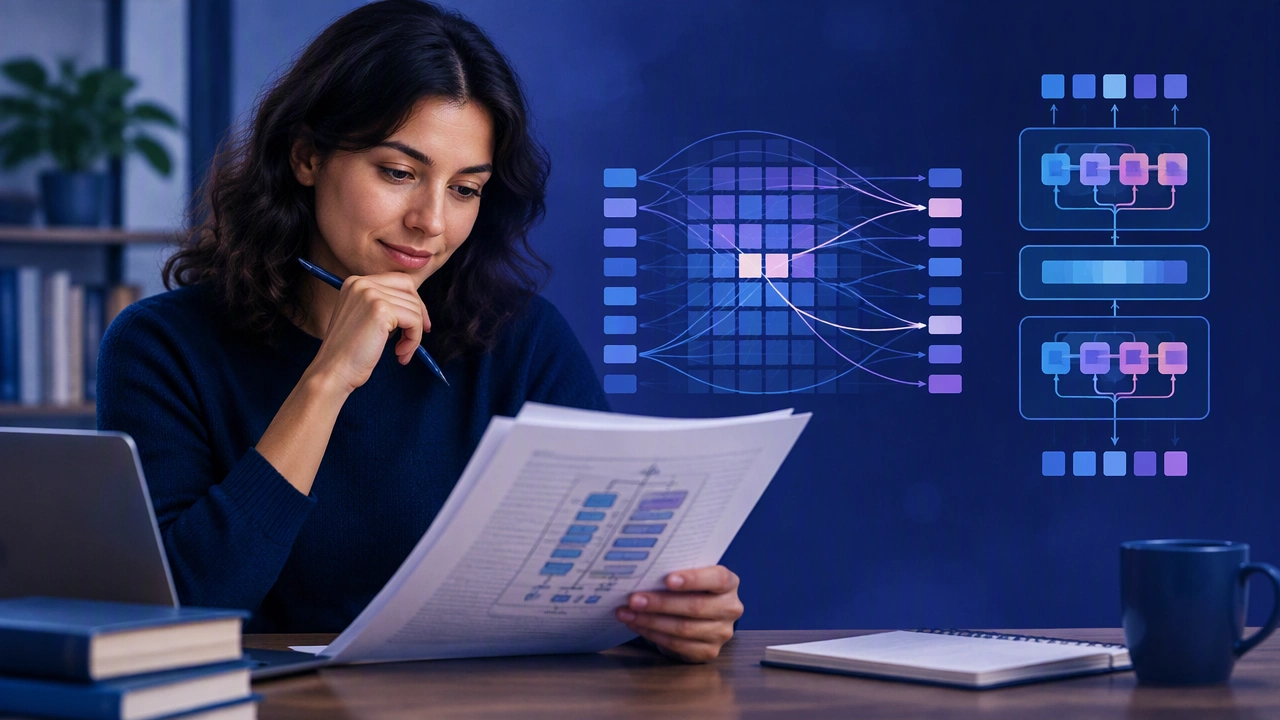
The 2017 paper Attention Is All You Need introduced the Transformer architecture, which now powers GPT, BERT, and virtually every modern language model. If you have ever wondered why this paper matters so much, here is a simplified walkthrough. Before Transformers, sequence models relied on recurrent networks that processed words one at a time, making them slow and bad at capturing long-range dependencies. The key innovation was the self-attention mechanism, which lets every word in a sentence look at every other word simultaneously and decide which ones matter most for context. The paper also introduced multi-head attention, positional encoding, and layer normalization, but the breakthrough idea is really about parallelization and context. Instead of reading left to right, the model considers the entire input at once. This is why Transformers scale so well with modern GPUs. I recommend reading the original paper alongside Jay Alammar’s illustrated blog post for the best understanding. What aspects of the architecture do you find most confusing?