How Convolutional Neural Networks Detect Patterns in Images
Artificial intelligence has made image recognition practical in everyday tools, from photo search to medical screening. At the heart of many of these systems are convolutional neural networks, a design inspired by how the visual cortex focuses on small regions, local contrasts, and repeating shapes. If you have been looking for a convolutional neural networks for image recognition tutorial, this article explains how filters, pooling layers, and feature maps work together to turn raw pixels into meaningful patterns.
Unlike a traditional program that checks hard-coded rules, a convolutional neural network learns to spot useful visual cues from examples. It does this by sliding small detectors across an image, summarizing what they find, and building a hierarchy of features. The result is a model that can generalize to new images, not just memorize the ones it has already seen.
Why images need a special kind of network
A color image is a three-dimensional grid of numbers: height, width, and color channels. A fully connected network that treats every pixel as an independent input ignores the fact that nearby pixels form edges, textures, and shapes. It also explodes in parameters, which makes training slow and overfitting likely.
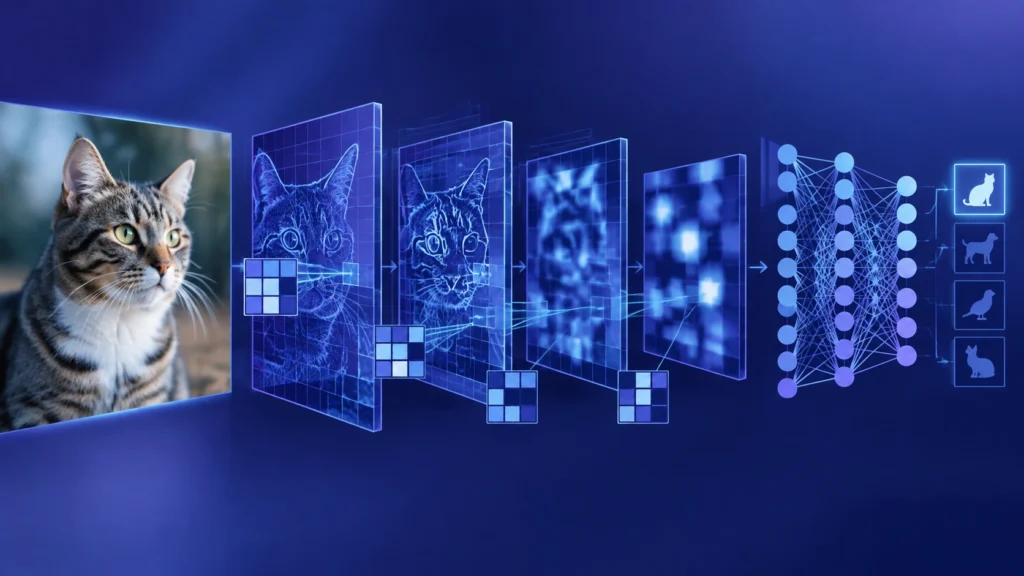
Convolutional layers solve this by looking at small neighborhoods at a time. They use filters, also called kernels, that slide across the image and respond to specific patterns, such as a vertical edge or a patch of color. Because the same filter is reused everywhere, the network learns compact, transferable detectors that respect the spatial structure of images.
Filters: small detectors that scan an image
A filter is a tiny matrix of weights, often 3×3 or 5×5. During a convolution operation, it moves across the image in steps called strides. At each position, it multiplies its weights by the underlying pixel values and sums the results, producing one number in an output map. That number reflects how strongly the local patch matches the pattern the filter has learned.
- Edge detectors respond to sharp changes in brightness, like the boundary between a dark sky and a bright building.
- Color contrast detectors react when one channel is much brighter or darker than another, highlighting transitions.
- Texture detectors combine simple edges to pick up repeating motifs such as fabric weave or grass.
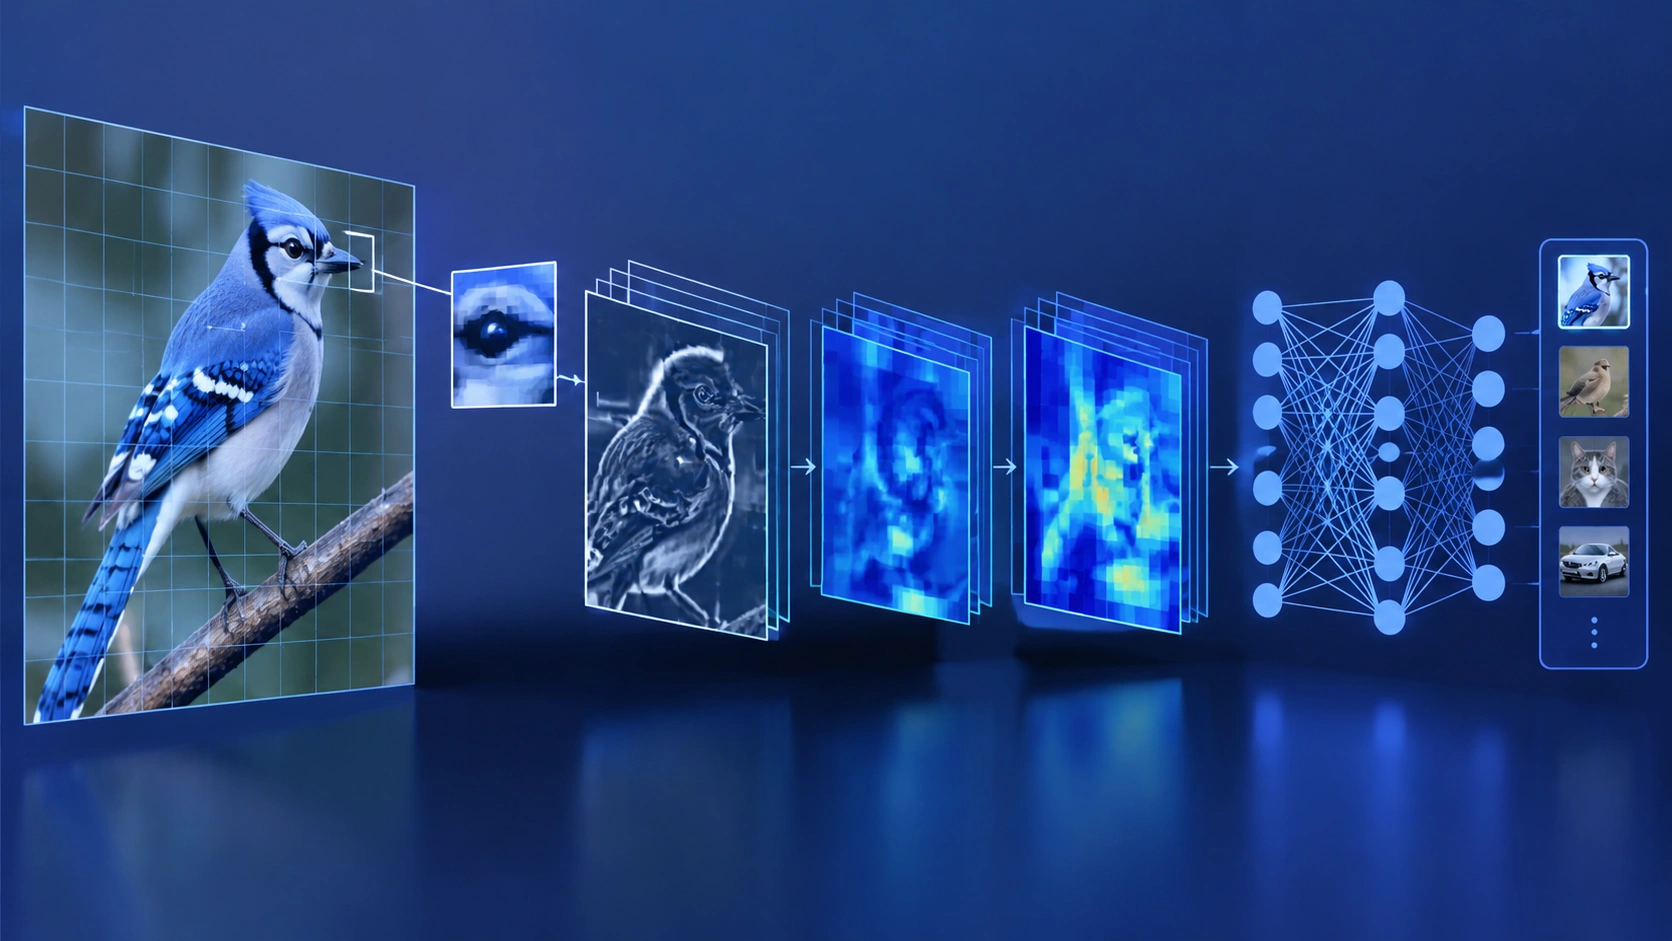
Early layers often learn simple cues like edges and colors. Deeper layers combine those cues into more complex features, such as corners, eyes, wheels, or letter strokes. This layered construction is what makes deep learning powerful for vision.
Feature maps: where detected patterns live
The output of a filter applied across the entire image is called a feature map. Each position in the map records the strength of the filter response at the corresponding location. If you imagine the original image as a photograph, a feature map is like a heatmap that highlights where a certain pattern occurs.
A convolutional layer usually applies many filters at once, producing a stack of feature maps. One map might emphasize horizontal edges, while another highlights red-to-green transitions. This stack gives the network a rich, multi-view representation of the same image. As you move deeper, feature maps encode increasingly abstract concepts, moving from lines to parts and then to objects.
Activation functions: adding nonlinearity
After convolution, networks typically apply a nonlinear activation function, most commonly ReLU (rectified linear unit). ReLU replaces negative values with zero while keeping positive values unchanged. This simple step lets the network model complex relationships rather than collapsing into a linear system. Nonlinearity is essential because real-world visual patterns rarely follow straight-line rules.
Pooling layers: summarizing and stabilizing
Pooling reduces the spatial size of feature maps, which cuts computation and helps the model focus on the most important signals. It also adds a degree of translation tolerance, meaning the network can recognize a pattern even if it shifts a few pixels.
- Max pooling takes the largest value in a small window, such as 2×2. It preserves the strongest activation, which often corresponds to the most salient local feature.
- Average pooling computes the mean in a window, giving a smoother summary that can reduce noise.
A typical pattern is to alternate convolution, activation, and pooling. After several rounds of this, the network has compact feature maps that capture high-level structure, such as the presence of an eye or a tire, with less sensitivity to exact pixel positions.
From feature maps to decisions
Once the convolutional and pooling layers have built a hierarchy of features, the network converts the final feature maps into a decision. Common approaches include:
- Global average pooling, which averages each feature map into a single number.
- Flattening, which unrolls the remaining spatial grid into a vector.
- Fully connected layers, which combine features to produce class scores.
A softmax function can turn those scores into probabilities for each class, such as cat, dog, or car. During training, the network compares these probabilities to the true label, computes an error, and updates the filter weights through backpropagation. Over many examples, the filters learn to detect the patterns that best separate the classes.
A simple mental model of the pipeline
Imagine feeding a photo of a bicycle into a small convolutional network:
- Layer 1 detects edges and color gradients.
- Layer 2 combines edges into corners, curves, and textures.
- Layer 3 assembles parts like spokes, handlebars, and frame tubes.
- Pooling compresses each stage, keeping strong signals and reducing exact positions.
- Final layers weigh the presence of these parts and predict bicycle with high confidence.
This progression from low-level cues to high-level concepts is the essence of how convolutional neural networks understand images.
Practical tips for beginners
If you are building your first image model, a few choices matter:
- Start with small filters. Stacked 3×3 filters are efficient and expressive.
- Use moderate stride and pooling. Aggressive downsampling can discard useful detail.
- Watch class balance. Imbalanced datasets bias the model toward the majority class.
- Apply data augmentation. Flips, crops, and color shifts help the network generalize.
- Monitor overfitting. If training accuracy rises while validation accuracy stalls, simplify the model or add regularization.
Clear evaluation also helps. Beyond overall accuracy, look at per-class precision and recall, and inspect confusion matrices to see which categories the model mixes up.
Why this design works so well
Convolutional neural networks succeed because they encode useful priors about images. They assume locality, meaning nearby pixels matter most; weight sharing, meaning the same detector can appear across the image; and hierarchy, meaning simple features combine into complex ones. These assumptions reduce the number of parameters, speed up learning, and improve generalization.
As a result, the same building blocks scale from small projects to large production systems. Whether you are classifying product photos, finding defects on a factory line, or assisting a radiologist with screening, filters, pooling layers, and feature maps provide a clear path from raw pixels to reliable predictions.
Key takeaways
- Filters are small learned detectors that slide over the image and respond to specific patterns.
- Feature maps record where each pattern appears and how strong it is.
- Pooling layers summarize spatial information, reduce computation, and add robustness to small shifts.
- Stacking these components builds a hierarchy from edges to parts to objects, enabling accurate image recognition.
With this foundation, you can approach more advanced topics like residual connections, depthwise separable convolutions, and attention mechanisms, all of which refine how networks see and interpret the visual world.